

tool_result, and those payloads add up fast.
A single Claude Code session can consume tens of thousands of tokens just from tool declarations and results.
And finally, the model’s responses add up. Filler, repetitive scaffolding, polite preambles, over-explanation, markdown overhead.
As a Gateway, Edgee has an easy access to all the data that flows through it, and can apply three strategies to compress the context: tool_result_trimming, tool_surface_reduction, and output_brevity.
Token compression V2
Reducing the number of tokens sent to and received from the LLM, without losing information from the model’s perspective. Compression is the surgical removal of redundancy, not summarization. Our compression strategies reduce token bills by 15-20% across active customers. Our SWE-bench Lite benchmark measures 50% with all three strategies on, but that is a controlled ceiling: see what you’ll actually save for why production sits lower. Two layers, treated as distinct:- Layer 1: Input compression (~99% of total token volume). What enters the context window: system prompts, tool results, codebase context, conversation history, MCP tool definitions.
- Layer 2: Output compression (~1% of total volume but high ROI). What the model generates: filler, repetitive scaffolding, polite preambles, over-explanation, markdown overhead.
Tool Result Trimming — improved in V2
Filters CLI and tool results before they reach the model. Strips boilerplate, pagination markers, ANSI escape sequences, repeated headers, and verbose framing. Initially based onrtk-ai/rtk, we built our tool result compression strategy directly into the Edgee Rust gateway, so users don’t need a separate binary in their pipeline.
On SWE-bench Lite, this cuts median per-task cost by 10.4%, with 4 of 6 tasks favoring Edgee. The signal is directional rather than statistically significant at that sample size, and the gains compound on long sessions where tool output piles up.
Tool Surface Reduction — new in V2
Coding agents connect multiple MCP servers, each exposing its own set of tools. The agent sends the full tool list to the model on every request, even when only one or two MCP servers are relevant. This bloats context and drives up cost. Edgee creates a virtual MCP server that the model sees. The virtual MCP classifies the user’s task and searches for the correct real MCP server to use. It sends the result back to the client, which then executes the real MCP server. The IDE still exposes all MCP servers; the agent still discovers tools through MCP, but the model only ever sees the virtual MCP. On SWE-bench Lite, this removes 33% of total tokens on tool-heavy MCP workloads, with 8 of 8 tasks favoring Edgee (p = 0.008). Cost falls around 10% rather than 33%, because the tokens it removes are cache reads, the cheapest class. If latency, throughput or context window is your binding constraint rather than the bill, the 33% is the number to look at.Output Brevity — new in V2
Reduces verbosity of model responses without losing technical content. Same answer, fewer tokens. Single flag — no level parameter. On SWE-bench Lite, this cuts median per-task cost by 27.5%, with 6 of 6 tasks favoring Edgee (p = 0.031). It is the strongest of the three on autonomous coding work: it attacks output, the most expensive token class, without touching the prefix or disturbing cache amortization.Route
Directing each request to the right LLM provider at the right time, with automatic fallback when something goes wrong.Per-request fallback and retry (hosted-only)
Auto-fallback on provider 5xx and timeouts. Configurable provider chain. Zero downtime from the agent’s perspective.Plan-cap continuity (hosted-only)
When you hit a Claude Pro/Max plan cap, Edgee falls back from the plan-based provider to an API-key-based provider (GLM, alternative model) so the session keeps going instead of hard-stopping. This is the layer no OSS tool currently fills end-to-end: OpenRouter and LiteLLM exist as API proxies, but they don’t serve users on Pro/Max plans (who pay Anthropic by subscription, not by API key).Observe
Comprehensive tracking of every token, request, compression event, and routing decision, across sessions, teams, and even at the GitHub repository or pull request level.Session-level metering
Log of every request, every compression event, every cost delta.Team-level metering and dashboard (hosted-only)
Cross-developer, cross-project, cross-session aggregation in the managed Edgee console. The OSS gateway emits the events; aggregation and visualization are part of the hosted product. Without observability, the other two pillars are flying blind. Compression savings can’t be tuned. Routing decisions can’t be evaluated. Cost-per-feature can’t be computed.The OSS ecosystem we credit
Token efficiency is a serious topic that an active OSS community is solving across multiple angles. We are part of that ecosystem.Receipts

Claude Code endurance test
+26.2% more instructions completed on the same Claude Pro plan. 20.8% more efficient per instruction. 5.1% cheaper per task on a cost-adjusted basis. Source:
edgee-ai/claude-compression-lab.
Codex re-read context benchmark
−49.5% fresh input tokens (1.14M → 574K per session). −35.6% total session cost (2.58). Cache hit rate 76% → 85%. Source:
edgee-ai/compression-lab.Where Edgee runs
The Edgee Gateway runs on all AWS regions. Requests are routed to the closest point of presence via DNS, no configuration required. The gateway is content-aware: it parses tool calls, tool results, and MCP definitions before any compression strategy fires.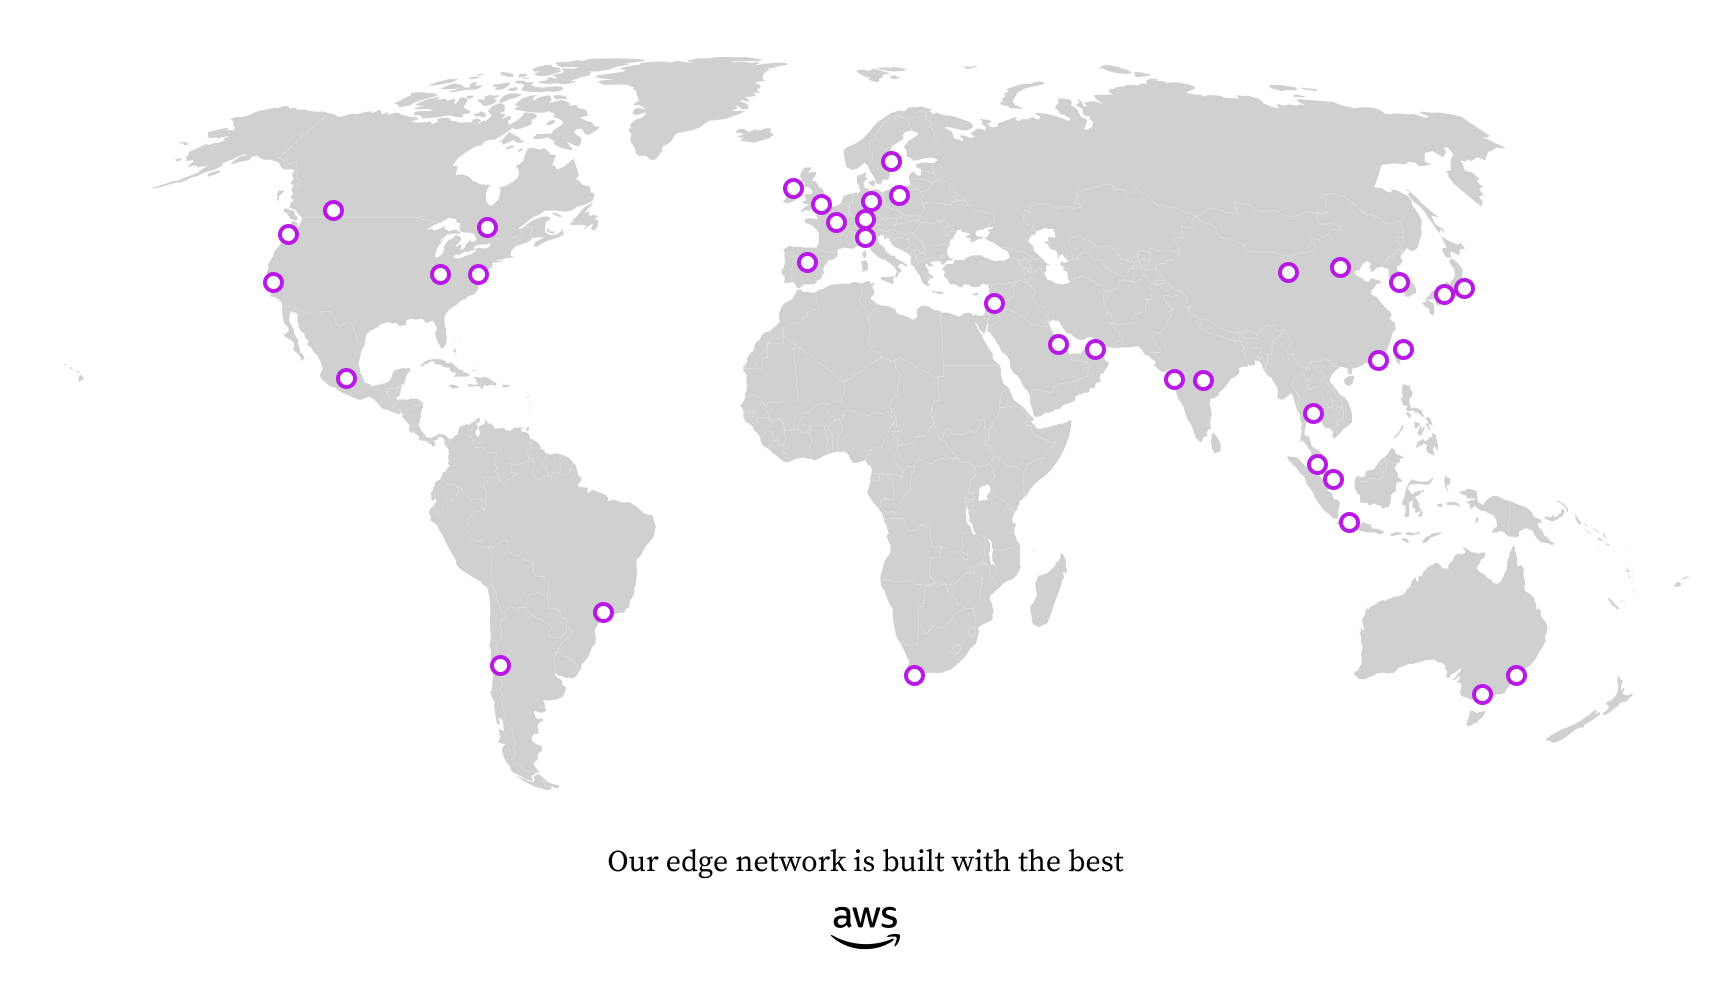
Next
FAQ
Questions we hear most often.
Quickstart
Install the CLI, launch your agent, see the receipts.